Showing posts with label HTTP. Show all posts

Friday, 14 April 2017

Future of CacheCow and the birth of CacheCore [Update: No CacheCore!]

CacheCow is my most popular OSS project which came to being back in 2012. It started its life as part of WebApiContrib but the need for a full-fledged project supporting different storage options soon led me to create CacheCow - which needed both client and server components.

With the availability of .NET Core which brings its completely new HTTP pipeline, the question has been when or how CacheCow will move to the .NET Core. On the client-side, HttpClient still is the king of making HTTP requests meaning CacheCow.Client will work when the long awaited .NET Standard 2.0 comes along allowing us to reference older .NET libraries. On the server-side, however, it is clear that CacheCow.Server has no place of existence since the pipeline in its entirety has been changed. So what should we do? Create a completely new project for both client-side and server-side or maintain CacheCow.Client (while migrating it to .NET Standard to support the new .NET) and create a new project for the server-side?

I have been thinking hard about this and for the reasons I will explain, I will be creating a completely new project called CacheCore (other contenders were Cache-vNext, CacheDnx and also recently CacheStandard) which will contain both client and server elements. [UPDATE: Please view newer announcement here]

If you would like to know the details (REST discussions, lessons learned including some gory confessions below) read the rest, otherwise feel free to watch the space as things will start to happen.

I am under no illusion that this will require quite some effort. Apart from the learning curve and niggles with tooling, I find the most frustrating aspect to be trying to google anything Core related: internet is now full of discarded evolutionary artifacts in the form of blogs, stackoverflow questions, tutorials and even MSDN documentation - each documenting the journey not the current state. If you think that is a small issue, ask anyone picking .NET Core for the first time. I wish we had a big giant flush and could have flushed all that to /dev/null wiping the history clean - never mind all those many many hours lost. OK, rant over - promise.

CacheCore.Server

As I said, I have confessions to make and one is just coming. When I designed server components of CacheCow as an API middleware, the idea was that they would be used for services that are purely RESTful in the sense that all changes to the state of the resource would be going through the API to carry out the state change. Initially there does not seem anything extra-ordinary about this but I gradually learnt that cache coherency is a very big responsibility for a mere middleware to take on.

First of all, there are many services out there that the underlying data could change without a request passing through the API. What is worse is that even if all state change is via API calls, the change to a resource could invalidate other resources. For example, a PUT request to /cars/123 will invalidate the /cars/123 which is fine, but what about ‘/cars’? So I started thinking about resources in terms of collection and instance and CacheCow.Server started to infer collection and instance resources based on a convention - hence I used Route Pattern concept so the application could configure the cache invalidation, so here route pattern would be /cars/*.

But the problem did not stop there. A change to /cars/123/contracts/456 could invalidate all these URLS: /cars/123/contracts, /cars/123 and possibly /cars - hence CacheCow now needs to walk up the tree and invalidate all those resources. And now to the next level of headaches: a POST /orders/1234 could invalidate customer/987 as there is no apparent connection unless the application tells us - which made me introduce the concept of Linked Route Patterns so the application could configure these relationships. And configuring was of course a pain, and frankly I think except me and a handful other people really did not quite get what I was on about.

Now, I believe it is too much of a responsibility for an HTTP middleware to do cache coherency. As such CacheCore.Server will be a lot simpler: no more entity tag storage, application will decide to use ETag or LastModifieDate for cache coherency and will be responsible for providing these values - although I will provide some helpers. One key difference in this implementation would be a set of tools fitting different scenarios rather than a single HTTP Caching god-class.

To explain this aspect further, HTTP caching is a spectrum of primitives that help you build more scalable (caching) and consistent (concurrency) systems - some of which are basic and used by many, while others have remained obscure and seldom used. Caching and expiry on resources are better known while from my experience, conditional PUT to achieve optimistic concurrency is rarely used - even conditional GET is rarely used by HTTP clients other than browsers. As such, CacheCore will come with three filters starting from the most basic to the most advanced:
  • BasicCacheFilter: This is the simplest filter which covers returning Cache-Control headers according to expiry configuration, reading the ETag or LastModified from the returned model (or inferring them by using reflection) and handling conditional GET for you. As long as you have a property called ETag or LastModified (or LastModifiedDate, etc) on the model you return from your API, this will work. For conditional GETs to this filter you would not save on any pressure your “database”: API calls will result on retrieval of data to the API so the filter can find the ETag or LastModified and accordingly respond to conditional GET requests.
  • LookupCacheFilter: This filter improves on the BasicCacheFilter by allowing the application to provide a callback mechanism for the application to look up ETag or LastModified without having to load the full model. Caching almost always gets used on resources where the operation is expensive either in IO or computation costs and this approach helps you to replace loading the full model with a light-weight lookup call. For example, let’s say the resource is /cars/123 and you keep a LastModifiedDate on your cars database and use hash of the LastModifiedDate as the ETag (you could use LastModifiedDate to do cache validation on the date but HTTP date’s precision is sadly up to a second which might not be enough for you). In this case, the filter will enquire the application for ETag or LastModified of the resource and you can call your database and read that value for car:id=123 without loading the whole car - which is going to be a lighter database call. So this filter will do all BasicCacheFilter (and in more efficient way) and will even do conditional PUT for you. What is the problem with this one? Consistency: in terms of conditional PUT, validation is not atomic, e.g. you look up the ETag and you find the condition is met and proceed to update meanwhile data could have changed between the lookup and update (same could also apply to conditional GET but has less serious impact). This is not a problem for everyone hence I think this filter hits the sweet spot for simplicity and effectiveness.
  • StrongConsistencyCacheFilter: This is basically the same as above but maintains airtight consistency by allowing the application to implement atomic conditional GET and PUT - which means application has to do more.
I have plans for these to be GET or PUT specific since actions are usually designed as such.
Now you might ask, why CacheCore is a filter and not a middleware? If you remember, CacheCow.Server was a DelegatingHandler (akin to an ASP.NET Core middleware). Well, here is another lesson learnt: caching is a highly localised concern, it is a mistake to implement it as a global HTTP intermediary.

CacheCore.Client

Considering the client story in .NET Core for HTTP has not been drastically changed, it is fair to assume CacheCow.Client can still be used.

That is true, however, there are a few reasons I would like to start afresh. First of all, CacheCow’s inception and the main of the codebase was designed when .NET yet did not have an await keyword. This resulted in a .ContinueWith() soup which was hard to read and difficult to maintain. On the other hand, some interfaces supported async while others did not, resulting in breaking the async all the way rule. Also I had in mind for the storage to be clever about how much storage it uses per site and implement LRU while many underlying storages did not provide the primitive to do so - and frankly in this 5 years I have never needed it.

I think it is time to get rid of these shortcomings hence there will be a new client project too.

Future of CacheCow.Server and CacheCow.Client

It would be naive to think everyone will move to .NET Core straightaway. In fact, with .NET Standard 2.0, Microsoft has shown to have realised there needs to be a better interoperability between the classic .NET and the .NET Core. Apart from interoperability, I think people will carry on using and building .NET APIs for another few years.

Fore these reasons, I will carry on supporting CacheCow and releasing bug fixes, etc. Thanks for helping it improve by using it, reporting issues and sending bug fixes.

Sunday, 10 May 2015

Machine Learning and APIs: introducing Mills in REST API Design

Level [C3]

REST (REpresentational State Transfer) was designed with the "state" at its heart, literally, standing for the S in the middle of the acronym.

TL;DR: Mill is a special type of resource where server's authority purely comes from exposing an algorithm, rather than "defining, exposing and maintaining integrity of a state". Unlike an RPC style endpoint, it has to adhere to a set of 5 constraints (see below). 

Historically, when there were only a few thousand servers around, the state was predominantly documents. People were creating, editing and sharing a lot of text documents, and some HTML. With HTTP 1.1, caching and concurrency was built into the protocol and enabled it to represent richer distributed computing concerns and we have been building . With the rising popularity of REST over the last 10 years, much of today's web has been built on top of RESTful thinking, whether what is visible or what is behind the presentation (most external layer) servers. Nowadays when we talk of state, we normally mean data or rather records persisted in a data store (relational or non-relational). A lot of today's data, directly or indirectly, is created, updated and deleted using REST APIs. And this is all cool, of course.

When we design APIs, we map the state into REST Resources. It is very intuitive to think of resources as collection and instance. It is unambiguous and useful to communicate these concepts when for example we refer to /books and /books/123 URLs, as the collection or instance resources, respectively. We interact with these resources using verbs, and although HTTP verbs are not meant to be used just for CRUD operations, interacting with the state that exists on the server is inherent in the design.

But that is not all the story. Mainstream adoption of Machine Learning in the industry means we need to expose Machine Learning applications using APIs. The problem is the resource oriented approach of REST (where the state is at the heart of the design) does not work very well.

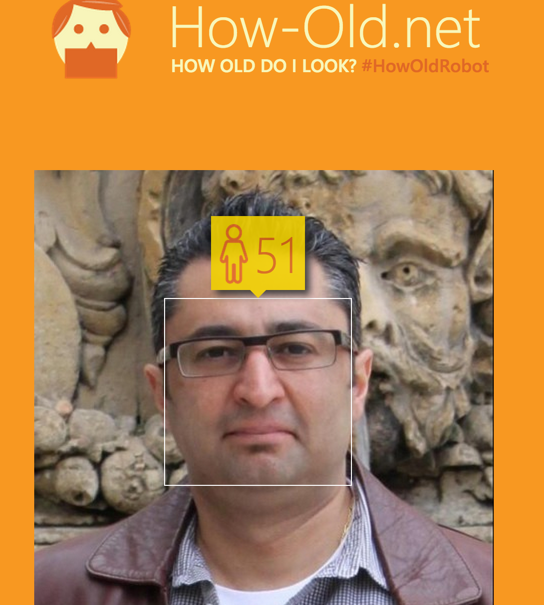
By the way, I am NOT 51...
How-old.net is an example of a Machine Learning application where instead of being an application, it could have been an API. For example (just for illustration, you could use other media types too):

POST /age_gender_classifier HTTP/1.1
Content-Type: image/jpeg
And the response:
200 OK
Content-Type: application/json

{
    "gender":"M"
    "age":37
}

Server is generating a response to the request by carrying out complex face recognition and running a model, most likely a deep network model. Server is not returning a state stored on the server, in fact this whole process is completely stateless.

And why does this matter? Well I feel if REST is supposed to move forward with our needs and use cases, it should define, clarify, internalise and finally digest edge cases. While such edge cases were pretty uncommon, with the rise and popularity of Machine Learning, such endpoints will be pretty standard.

A few days ago, on the second day of APIdays Mediterranea 2015 conference, I presented a talk on Machine Learning and APIs. And in this talk I presented simple concept of Mills. Mills, where you take your wheat to be ground and you carry back the flour.


Basically, it all goes back to the origin of a server's authority. To bring an example, a "Customer Profile" service, exposed by a REST API, is the authority to go to when another service requires access to a customer's profile. The "Customer Profile" service has defined a state, which is profile of the customers, and is responsible for ensuring integrity of the state (enforcing business rules on the state). For example, marketing email preference can have values of None, WeeklyDigest or All, it should not allow the value to be set to MonthlyDigest. We are quite used to these type of services and building REST APIs on top: CustomerProfile becomes a resource that we can query or interact with.

On the other hand, a server's authority could be exposing an algorithm. For example, tokenisation of text is a non-trivial problem that requires not only breaking the text to its words, but also maintaining muti-words and named entities intact. A REST API that exposes this functionality will be a mill.

5 constraints of a Mill

1) It encapsulates an algorithm not a state

Which was discussed ad nauseum, however, the distinction is very important. For example let's say we have an algorithm that you provide the postcode and it returns to you houses within 1 mile radius of that postcode - this is not an example of a mill.

2) Raw data in, processed data out

For example you send your text and get back the translation.

3) Calls are both safe and idempotent

Calling the endpoint should not directly change any state within the server. For example, the endpoint should not be directly mapped to the ML training engine, e.g. sending a text 1000 times skew the trained model for that text. The training endpoint is usually a normal resource, not a mill - see my slides

4) It has a single specialty

And as such, it accepts a single HTTP verb apart from OPTIONS, normally POST (although a GET with entity payload would be more semantically correct but not my preferred option for practical reasons).

5) It is named not as a verb but as a tool

A mill that exposes tokenisation, is to be called tokeniser. In a similar way, classifier would be the appropriate name for a system that classifies on top of a neural network, for example. Or normalising text, would have a normaliser mill.


No this is not the same as an RPC endpoint. No RPC smell. Honest :) That is why those 5 constraints exists.


Tuesday, 3 June 2014

Cancelling an async HTTP request Task sends TCP RESET packet

Level [T4]

This blog post did not just happen. In fact, never, if ever, something just happens. There is a story behind everything and this one is no different. Looking back, it feels like a nice find but as the story was unfolding, I was running around like a headless chicken. Here we have the luxury of the hindsight so let's take advantage of it.

TLDR; If you are a sensible HTTP client and make your HTTP requests using cancellable async Tasks by passing a CancellationToken, you could find your IP blocked by legacy bridge devices blacklisting clients sending TCP RESET packets.

So here is how it started ...

So we were supposed to go live on Monday - some Monday. Talking of live, it was not really live - it was only to internal users but considering the high profile of the project, it felt like the D-Day. All VPs knew of the release and were waiting to see a glimpse of the project. Despite the high profile, it was not properly resourced, I despite being so called architect , pretty much singled handedly did all the API and the middleware connecting the Big Data outputs with the Single Page Application.

We could not finish going live on Monday so it moved to Tuesday. Now on Tuesday morning we were all ready and I set up my machine's screen like traders with all performance monitors up on the screen looking at users. With using the cloud Azure, elasticity was the option although the number of internal users could hardly make a dent on the 3 worker roles. So we did go live, and, I could see traffic building up and all looked fine. Until ... it did not.

I saw requests queuing up and loading the page taking longer and longer. Until it was completely frozen. And we had to take the site down. And that was not good.

Server Analysis

I brought up DebugView and was lucky to see this (actual IP and site names anonymised):

[1240] w3wp.exe Error: 0 :
[1240] <html>
[1240] <h1>Access Administratively Blocked</h1>
[1240] <br>URL : 'http://www.xyz.com/services/blahblah'
[1240] <br>Client IP address : 'xyz.xx.yy.zzz'
[1240] </html>

So we are being blocked! Something is blocking us and this could be because we used an UI data endpoint as a Data API. Well I knew it is not good but as I said we had a limited time and in reality that data endpoint was meant to support our live traffic.

So after a lot of to and fro with our service delivery and some third party support, we were told that our software was recognised as malicious since it was sending way too many TCP RESET packets. Whaa?? No one ain't sending no TCP whatever packets, we are using a high level language (C#) and it is the latest HttpClient implementation. We are actually using many optimising techniques such as async calls, parallelisation, etc to make the code as efficient as possible. We also used short timeout+ retry which is Netflix's approach to improve performance.

But what is TCP RESET packets? Basically a RESET packet is one that has the RESET flag set (which is otherwise unset) and tells the server to drop the TCP connection immediately and reclaim all the resources associated with it. There is an RFC from back in 2002 that considers RESET harmful. Wikipedia's article argues that when used as designed, it is useful but forged RESET can disrupt the communication between the client and server. And Microsoft's technet blog on the topic says "RESET is actually a good thing".

And in essence, I would agree with the Microsoft (and Wikipedia's) account that sending RESET packet is what a responsible client would do. Let's imagine you are browsing a site using a really bad wifi connection. The loading of the page takes too long and you frustrated by the slow connection, cancel browsing by pressing the X button. At this point, a responsible browser should tell the server it has changed its mind and is not interested in the response. This will let the server use its resources for a client that is actually waiting for the server's response.

Now going back to the problem at hand, I am not a TCP expert by any stretch - I have always used higher level constructs and never had to go down so deep in the OSI model. But my surprise was, what is different now with my code that with a handful calls I was getting blocked while the live clients work well with no problem with significantly larger number of calls?

I had a hunch that it probably has to do with the some of the patterns I have been using on the server. And to shorten the suspense, the answer came from the analysis of TCP packets when cancelling an async HTTP Task. The live code uses the traditional synchronous calls - none of the fancy patterns I used. So let's look at some sample code that cancels the task if it takes too long:

var client = new HttpClient();
var buffer = new byte[5 * 1000 * 1000];
// you might have to use different timeout or address
var cts = new CancellationTokenSource(TimeSpan.FromMilliseconds(300)); /
try
{
    var result = client.GetAsync("http://www.google.com",
    cts.Token).Result;
    var s = result.Content.ReadAsStreamAsync().Result;

    var result1 = s.ReadAsync(buffer, 0, buffer.Length, cts.Token).Result;
    ConsoleWriteLine(ConsoleColor.Green, "Got it");
}
catch (Exception e)
{
    ConsoleWriteLine(ConsoleColor.Red, "error! " + e);
}

In this snippet, we are calling the google server and set a 300ms timeout (which you might have to modify the timeout or the address based on your connection speed, in order to see the cancellation). Here is a WireShark proof:


As you can see above a TCP RESET packet has been sent - if you have set the parameters in a way that the request does not complete before its timeout and gets cancelled. You can try this with a longer timeout or use a WebClient which is synchronous and make sure you will never ever see this RST packet.

Now the question is, should a network appliance pick on this responsible cancellation and treat it as an attack? By no means. But in my case, it did and it is very likely that it could do that with yours.

My solution came by whitelisting my IP against "TCP RESET attacks". After all, I was only trying to help the server.

Conclusion

Cancelling an HTTP async Task in the HttpClient results in sending TCP RESET which is considered malicious by some network appliances resulting in blacklisting your IP.

PS. The network appliance belonged to our infrastructure 3rd party provider whose security managed by another third party - it was not in Azure. The real solution would have been to remove such crazy rule, but anyhow, we developers don't always get what we want.


Saturday, 19 April 2014

CacheCow 0.5 Released

[Level T1]

OK, finally CacheCow 0.5 (actually 0.5.1 as 0.5 was released by mistake and pulled out quickly) is out. So here is the list of changes, some of which are breaking. Breaking changes, however, are very easy to fix and if you do not need new features, you can happily stay at 0.4 stable versions. If you have moved to 0.5 and you see issues, please let me know ASAP. For more information, see my other post on Alpha release.

So here are the features:

Azure Caching for CacheCow Server and Client

Thanks to Ugo Lattanzi, we have now CacheCow storage in Azure Caching. This is both client and server. Considering calls to Azure Cache takes around 1ms (based on some ad hoc tests I have done, do not quote this as a proper benchmark), this makes a really good option if you have deployed your application in Azure. You just need to specify the cacheName, otherwise "default" cache will be used.

Complete re-design of cache invalidation

I have now put some sense into cache invalidation. Point is that strong ETag is generated for a particular representation of the resource while cache invalidation happens on the resource including all its representation. For example, if you send application/xml representation of the resource, ETag is generated for this particular representation. As such, application/json representation will get its own ETag. However, on PUT both need to be invalidated. On the other hand, in case of PUT or DELETE on a resource (let's say /api/customer/123) the collection resource (/api/customer) needs to be invalidated since the collection will be different. 

But how we would find out if a resource is collection or single? I have implemented some logic that infers whether the item is collection or not - and this is based on common and conventional routes design in ASP.NET Web API. If your routing is very custom this will not work. 

Another aspect is hierarchical routes. When a resource is invalidated, its parent resource will be invalidated as well. For example in case of PUT /api/customer/123/order/456 , customer resource will change too - if orders are returned as part of customer.  So in this case, not only the order collection resource but the customer needs to be invalidated. This is currently done in CacheCow.Server and will work for conventional routes.

Using MemoryCache for InMemory stores (both server and client)

Previously I have been using dictionaries for InMemory stores. The problem with Dictionary is that it just grows until system runs out of memory while MemoryCache limits its use of memory when system deals with a memory pressure.

Dependency of CachingHandler to HttpConfiguration

As I announced before, you need to pass the configuration to he CachingHandler on server. This should be an easy change but a breaking one.


Future roadmap and 0.6

I think we are now in a point where CacheCow requires a re-write for the features I want to introduce. One of such features is enabling Content-based ETag generation and cache invalidation. Currently Content-based ETag generation is there and can be used now but without content-based invalidation is not much use especially that in fact this now generates a weak ETag. Considering the changes required for achieving this, almost a re-write is required.

Please keep the feedbacks coming. Thanks for using and supporting CacheCow!


Sunday, 1 December 2013

CacheCow 0.5.0-alpha released for community review: new features and breaking changes

[Level T3]

CacheCow 0.5 was long time coming but with everything that was happening, I am already 1 month behind. So I have now released it as alpha so I can get some feedback from teh community.

As some of you know, a few API improvements had been postponed due to breaking changes. On the other hand, there were a few areas I really needed to nail down - the most important one being resource organisation. While resource organisation can be anything, most common approach is to stick with the standards Web API routing, i.e. "/api/{controller}/{id}" where api/{controller} is a collection resource and api/{controller}/{id} is an instance resource.

I will go through some of the new features and changes and really appreciate if you spend a bit of time reviewing and sending me feedbacks.

No more dependency on WebHost package

OK, this has been asked by Darrel and Tugberk and only made sense. So in version 0.4 I added dependency to HttpConfiguration but in order not to break the compatibility, it would use GlobalConfiguration.Configuration in WebHost by default. This has been removed now so an instance of HttpConfiguration needs to be passed in. This is a breaking change but fixing it should be a minimal change in your code from:
var handler = new CachingHandler(entityTagStore);
config.MessageHandlers.Add(handler);
You would write:
var handler = new CachingHandler(config, entityTagStore);
config.MessageHandlers.Add(handler);

CacheKeyGenerator is gone

CacheKeyGenerator was providing a flexibility for generating CacheKey from resource and Vary headers. Reality is, there is no need to provide extensibility points. This is part of the framework which needs to be internal. At the end of the day, Vary headers and URL of the resource are important for generating the CacheKey and that is implemented inside CacheKey. Exposing CacheKeyGenerator had lead to some misuses and confusions surrounding its use cases and had to go.

RoutePatternProvider is reborn

A lot of work has been focused on optimising RoutePatternProvider and possible use cases. First of all, signature has been changed to receive the whole request rather than bits and pieces (URL and value of Vary headers as a SelectMany result).

So the work basically looked at the meaning of Cache Key. Basically we have two connected concepts: representation and resource. A resource can have many representations (XML, image, JSON, different encoding or languages). In terms of caching, representations are identified by a strong ETag while resource will have a weak ETag since it cannot be guaranteed that all its representations are byte-by-byte equal - and in fact they are not.

A resource and its representations

It is important to note that each representation needs to be cached separately, however, once the resource is changed, the cache for all representations are invalidated. This was the fundamental area missing in CacheCow implementation and has been added now. Basically, IEntityTagStore has a new method: RemoveResource. This method is pivotal and gets called when a resource is changed.

The change in RoutePatternProvider is not just a delegate, it is now an interface: IRoutePatternProvider. Reason for the change to delegate is that we have a new method in there too: GetLinkedRoutePatterns. So what is a RoutePattern?

RoutePattern is basically similar to a route and its definition conventions in ASP.NET, however, it is meant for resources and their relationships. I will write a separate post on this but basically RoutePattern is in relation to collection resources and instance resources. Let's imagine a car API hosted at http://server/api. In this case, http://server/api/car refers to all cars while http://server/api/car/123 refers to a car with Id of 123. In order to represent this, we use * sign for collection resources and + sign for instance:

http://server/api/car         collection         http://server/api/car/*
http://server/api/car/123     instance           http://server/api/car/+  

Now normally:

  • POST to collection invalidates collection
  • POST to instance invalidates both instance and collection
  • PUT or PATCH to instance invalidates both instance and collection
  • DELETE to instance invalidates both instance and collection

So in brief, change to collection invalidates collection and change to instance invalidates both.

In a hierarchical resource structure this can get even more complex. If /api/parent/123 gets deleted, /api/parent/123/* (collection) and /api/parent/123/+ will most likely get invalidated since they do not exist any more. However, implementing this without making some major assumptions is not possible hence its implementation is left to the CacheCow users to tailor for their own API.

However, since a flat resource organisation (defining all resources using "/api/{controller}/{id}") is quite common, I have implemented IRoutePatternProvider for flat structures in ConventionalRoutePatternProvider which is the default.

Prefixing SQL Server Script names with Server_ and Client_

The fact was that SQL Server EntityTagStore (on the server package) and CacheStore (on the client package) had some stored procedure name clashes preventing use of the same database for both client and server component. This was requested by Ben Foster and has been done now.

Please provide feedback

I hope this makes sense and waiting for your feedbacks. Please ping me on twitter or ask your questions in Github by raising issue.

Happy coding ...

Sunday, 27 October 2013

REST APIs and restaurants [Take II*]

[Level C3]


 - "... and sauteed with the finest aromatic saffron - we import directly from our suppliers in Tibet - and garnished with the finest quality ocra from the heart of Morocco and ..."

- : ".. hmmm, bu..."

- : " and Sir, the King Shrimps day fresh from our suppliers in Belgium mildly cooked with a hint of lime zest and aromatic Thai basil snuggled with a swirl of Cornish Creme Fraiche and blossoms of Burmese jasmine and ..."

- : "... I mean, ..."

- : " and I should remind you that our head chef has used a special blend of exotic spices, marinated for 42 minutes exact, to create a sensual oriental effect of ... "

- : "I REALLY DON'T CARE! This stuff is awful!"


⚑  ⚑  ⚑

In more than one way a REST API is similar to a restaurant. They both hide a very complex process of accomplishing a service (serving food or data) behind a nice, warm and welcoming presentation. And we need to bear in mind that presentation is the key: no matter what goes on behind the scene in the kitchen, the food and its presentation is the key. And your API is the menu, the door to the services provided by the server. Whatever goes on in the kitchen (your server's internal domain) is not the concern of your customers as long as the output and presentation is good.

Commonly, the perspective in which we look at our services is wrong. They are server-centric. [I have talked before about the definition of server (and client) and their interaction] In brief, when we talk about the server, this is what comes in mind (as per CSDS):


This view is useful when building a server. It highlights inherent complexity of the server and how it should hide its complexity behind its API. But it is way too easy to get attached to the bird's eye view of the server where all internals of the server is visible.

And it is too easy to forget that this is how the client sees the server:

Client perspective of a server, where it sees a black box (here it's blue!) and
the gateway to the server is through its API.
When talking of the domain in an API, we are very likely to mean the server's private domain - its internals and complex process. Reality is server's internal domain does not surface beyond the API layer. API Layer is responsible to define resources which in turn define a coherent public domain composed of API and its messages - abstracted away from server's internal domain. If the server is an online retail API, I can create, edit or cancel orders. The fact that this is achieved through contact to many suppliers and their own custom processes is not a concern of the client.

In fact, in the same way that kitchen of a restaurant and its dining area are completely abstracted away, server's public domain is an abstraction on the top of server's internal domain. This is good for the chef and the customer. It is true the food that is served comes out of the kitchen but the whole process of preparation is irrelevant for the customer. 

Why talking of server's public domain is important? Because we commonly look down on the public domain. When we talk of the DTO messages passed to and fro, we regard them as View Models so they are not even proper models, they are just DTOs, no behaviour just some property bag. We use a mapper to strip down the sensitive data from our real models and spit out the view models to the client. And when we talk about DDD, we only mean server - we think view models do not deserve the love of care of DDD.

But this results in a brittle API that has to be changed by every change of the server. It becomes a cut down version of the server's internal API. We all know examples of good and bad API but too many changes in an API is a sign of bad design usually from Server Chauvinism. So always do a separate DDD for your server's public domain. It might sound strange since I am in favour of no-business-logic-in-api-layer. Well, it is true - we do not implement any business logic in the API Layer but the biggest responsibility of API Layer is talking HTTP. This translates to defining resources in REST.

So practice DDD in your API Layer. Define its aggregate roots, entities and value types - it is simplistic to think such concepts can be entirely hidden from the clients. Specify the commands and queries - with commands usually being the payload of the PUT, DELETE and POST and queries usually expressed in the URL itself to make them cache friendly.


What we see in the above picture define server's public domain: it is API (set of resources), input messages (commands and queries) and output messages (entities and value types). The case of queries - as we said - is a bit special since it is normally expressed in URL. This has the benefit of cacheability in contract with sending a payload (using other methods) which not suitable for caching. As an example, here is twitter's API for getting status timelines:

Get /1.1/statuses/user_timeline.json?screen_name=twitterapi&count=2

Defining parameters as query strings is useful as they can also imply optionality. One downside to this approach is the fact that ordering of parameters cannot be expressed in query string and while any combination can be valid, semantically equal combinations will be considered different resources and cached separately. For example, screen_name=twitterapi&count=2 and screen_name=twitterapi&count=2 are semantically equal while they are considered different resources. This reduces effectiveness of caching for GET requests. For this reason, URL segments separated by / are superior although in a big API can result in prohibitive complexity of routing.

Items returned in this API are Entities. it is evident by having an ID (id_str) which is returned as part of data.


Looking at what each timeline contains, we can see list of urls, where each url returned is a Value Type. It has three properties: url, indices and expanded_url.

In the case of commands, we have a similar situation. Looking at an example in twitter, tweeting (sending a tweet) is achieved using this command:

POST /1.1/statuses/update.json

status=Maybe%20he%27ll%20finally%20find%20his%20keys.%20%23peterfalk

Perhaps a better implementation would have been to omit the update.json totally - as this naming has an RPC smell. Using singular or plural is mainly down to taste - although I prefer singular. The command can be expressed by the simple class below:


Not all commands have to have a payload. Deleting a tweet can get send an ID in the URL with the DELETE command to /1.1/statuses/update.json although actual twitter API uses a POST instead.

Resources are basically all that can be accessed through the API although a more useful definition is the grouping around identities. For example Flickr API defines cameras, people, photos, photo comments, etc. It is true that Flickr is not considered a good example of a REST API when it comes to HTTP semantics, however, it does a good job in defining a coherent domain represented by resources while hiding its internals. A simple example is how it sends you previous and next photo instead of letting the client guess what these are based on the internal implementations.

In brief, it is responsibility of the API to create a coherent set of resources that can layout a cohesive picture in front of the client.

Common Anti-Patterns

As we said, the main danger is to have a server-centric perspective and neglect the public domain of your API.

While performing appropriate-sized DDD exercise is important, we need to be careful not expose too much of the server. One common anti-pattern is exposing server's internal to outside world. OData is a RESTful protocol which defines semantics for querying (mainly tabular) data store.

GET /api/products?$filter=name eq 'Gizmo 3'&$orderby=price desc&$top=1

While OData itself is not necessarily prescribing exposing server's internals, most of the implementations are actually built straight on the top of an RDBMS exposing its internal schema and and potentially allowing ad-hoc changes using SQL-like commands rather than domain-rich commands. Netflix who initially warmed up to the idea of exposing its films database to the public, reached the conclusion this is not such a RESTful idea and retired its OData service.

Another issue is the server-centric design: server assuming how its services will be used. I believe (Sorry Roy!) HATEOAS touches the subjects discussed here. When we talk of Hypermedia As The Engine OF Application State, which application do we mean? OK, let's consider Twitter's API. How can you think same hypermedia can equally drive the state of a twitter client, a game that posts scores on twitter, 4Square app that declares you a mayor on twitter or a twitter realtime map showing location of tweets using the firehose data pipe? The relationship from clients to servers are not one-to-one any more and effectiveness of HATEOAS is questionable. Application is defined by the client and not the server, as such server's hypermedia cannot be the engine of the application.

At the end of the day, none of us want to sound like the pompous chef who bores the customers with self-flattery. Server serves, so design it for servant-hood.


* this post was originally posted slightly differently under the name: "Server Chauvinism - API's public domain"

Sunday, 13 October 2013

CacheCow update - Moving to MemoryCache for in-memory stores on both Client and Server

As you might know, CacheCow is a framework that implements HTTP Caching for ASP.NET Web API both for the client and server. If you are familiar with it, feel free to jump to the section "What's the update?".

HTTP Caching defined by HTTP Specification (currently at version 1.1 according to RFC 2616 although the work HTTP 2.0 is very close to finish) is an important feature of HTTP resulting in scalability of web as we know it.

It is important to remember that resources are cached on the client, and not on the server. In ASP.NET we can use Output Caching and System.Web.Caching.Cache to cache items on the Server but HTTP caching is different in the fact that resources get stored on the client. A resource is

  • either not cacheable (identified by no-store value in the Cache-Control header)
  • or can be only cached by the client (identified by private value in the Cache-Control header)
  • or can be cached by the client and all intermediaries (identified by public value in the Cache-Control header)
Currently CacheCow.Client looks after the storage of the items in an implementation of ICacheSore interface. Currently these implementations exist:
  • In-memory
  • Memcached
  • Redis
  • SQL Server
  • File-based
On the other hand, server also needs to store cache metadata. This is normally information such as Last-Modified and ETag of the resources. You configure CacheCow.Server to use one of several implementations of IEntityTagStore on the server. Currently these implementations exist:
  • In-memory
  • Memcached
  • RavenDB
  • MongoDB
  • SQL Server

So what is the change?

In the latest release of CacheCow which stands at 0.4.12, in-memory implementation of ICacheStore and IEntityTagStore have been changed from ConcurrentDictionary<TKey, TValue> based to MemoryCache based. The problem with dictionary-based implementation is that the store just grows and the items will never be freed. MemoryCache, on the other hand, is designed to be able to keep its memory usage to a threshold and expel old or least frequently used items out of the cache. 

To use in-memory stores, all you have to do is to use the CachingHandler with default constructor which results in-memory stores to be used, as they are default. The good thing with these implementations are ability to set a maximum memory limit. This is achieved using app.config to web.config of your application:

<?xml version="1.0" encoding="utf-8" ?>
<configuration>
  <system.runtime.caching>
    <memoryCache>
      <namedCaches>
        <add name="TheName" cacheMemoryLimitMegabytes="40" pollingInterval="00:05:00" />
      </namedCaches>
    </memoryCache>
  </system.runtime.caching>
</configuration>

Above configuration will set the memory usage limit to 40MB and this limit will be checked every 5 minutes. CacheCow uses these names for its MemoryCache objects:

  • CacheCow.Client: "###InMemoryCacheStore_###"
  • CacheCow.Server uses 2 MemoryCache objects:
    • Storing ETag and LastModified: "###_InMemoryEntityTagStore_ETag_###"
    • Storing route patterns: "###_InMemoryEntityTagStore_RoutePattern_###"

You can use the configuration to limit the memory used by these MemoryCache objects. Since MemoryCache is in-memory and is in the same AppDomain as the application, it provides the fastest and most efficient storage.

Use in-memory storage wherever you can and surely it provides better performance compared to the likes of SQL Server.
The only caveat with using these implementations is that even though you may set a memory limit, memory can increase above your threshold. This is not an issue and is related to garbage collection and using GC.Collect() the memory will return back to the actual usage.

Sunday, 18 August 2013

OWIN and Katana challenges: blues of a library developer

[Level T4] I have to be very careful on how to phrase what I am about to write here. The .NET community celebrates OWIN's integration into .NET HTTP frameworks such ASP.NET Web API, NancyFx and others. This is the result of months and months of hard work and sleepless nights. While I am also jubilant to see this happening, we need to stay objective and keep a self-critical attitude to ensure we make the best of this opportunity. 

TLDR;

Developing a middleware library on top of OWIN that can be equally used by native frameworks is possible but at the current state far from ideal as the overhead of translation between different frameworks can be big. OWIN application and middleware are clearly defined as separate entities in the spec while they are regarded the same in the OWIN implementation itself which renders the distinction redundant.

Introduction

OWIN (Open Web Interface for .NET) is a community effort led by Benjamin Vanderveen and Louis Dejardin to "decouple server and application and, by being an open standard, stimulate the open source ecosystem of .NET web development tools". OWIN consists of a specification which is currently at version 1.0, a set of extension specifications and a small library owin.dll.

Katana is a project lead by Microsoft which provides implementation on top of minimal owin.dll implementation for abstractions such as OwinResquest, OwinResponse and OwinMiddleware. It also provides an HTTP server built on top of HttpListener.

Now each web platform also provides its own plumbing to OWIN.

What OWIN has nailed it

As we saw, the goal of OWIN has been defined as below:

The goal of OWIN is to decouple server and application and, by being an open standard, stimulate the open source ecosystem of .NET web development tools.
There is absolutely no doubt that OWIN has successfully delivered this promise. Regardless of what Server you are using (IIS, Kayak, HttpListener, etc) you can use web framework of choice.


Now this is all well and good. But we do expect more from OWIN. We would like to be able to write a middleware once and use it in any framework. There are many examples of this but main ones are security, formatting, caching, conneg, and alike. This all seemed easy and accessible to me so I set out to implement CacheCow as an OWIN middleware. But the task proved more convoluted than I though.

OWIN application and middleware

Here are how OWIN's application and middleware are defined:
Web Application – A specific application, possibly built on top of a Web Framework, which is run using OWIN compatible Servers.
Middleware – Pass through components that form a pipeline between a server and application to inspect, route, or modify request and response messages for a specific purpose.

Based on the specification (and definition above), an OWIN runtime can be viewed as below: 


Now if we look at the Application Startup section of the sepc, we see applicatrion as the engulfing runtime of the functionality. This is the interface for "application" startup:

public interface IAppBuilder
{

    IDictionary<string, object> Properties { get; }

    IAppBuilder Use(object middleware, params object[] args);

    object Build(Type returnType);

    IAppBuilder New();
}

So our view would probably change to this:


But after more digging, we realise that this cannot represent the use cases because:
  • It is possible to have an application which mixes different web frameworks, i.e. register multiple frameworks each covering a route. Now in this case, is application is composed of all smaller applications or each one is an application?
  • It is possible to have middlewares each based on a different framework. So similar to applications, they can based on a framework.
  • Middlewares does not have to be pass-through, they can be prematurely terminate pipeline chain.
  • Applications can be pass-through. This has been mainly implemented as 404-based chain of responsibility but any implementation is possible.
  • IAppBuilder does not have a notion of application - only middleware. There is no explicit means of registering an application and .Use method has a middleware parameter. Now we all know that this is also meant for applications and all extension methods currently available register applications such as .UseWebApi and .UseNancy.
So in essence, it seems like "application" is a redundant abstraction as far as runtime is concerned. This has no representation in OWIN code and I personally would like it to be removed from the spec or alternatively the definition of middleware and application merged for clarity. So this is how I see OWIN runtime:


ASP.NET Web API and OWIN HTTP Pipeline: Impedance mismatch

ASP.NET Web API provides a very powerful HTTP Pipeline expressed as SendAsync method below:

public Task<HttpResponseMessage> SendAsync(
 HttpRequestMessage request, CancellationToken cancellationToken
)

For those who have worked this pipeline it is clear that building a "middleware" as a DelegatingHandler is very easy.

On the other hand, OWIN provides a similar pipeline with this AppFunc signature:

using AppFunc = Func<
        IDictionary<string, object>, // Environment
        Task>; // Done

In this one, the operation is more or less the same since both request and response exist as part of the dictionary passed in.

As such, one might think that a DelegatingHandler should be very easy to convert to OWIN middleware. I personally expected this to take a few hours and set out to implement CacheCow as an OWIN middleware and show it off in a NancyFx app. I wish that was the case, but as I dig deeper it turned out we are facing hard challenges. At first googling around found this exact question, but to my surprise I found that .UseHttpMessaageHandler() (where a simple handler is returning data) and .UseWebApi() (where a whole ASP.NET Web API application is being set up) have been implemented yet no .UseDelegatingHandler() in site. That did not discourage me as I set out to build one using this little experimental rough and ready bridge:

public class OwinHandlerBridge : HttpMessageHandler
{
    private readonly DelegatingHandler _delegatingHandler;
    private readonly FixedResponseHandler _fixedResponseHandler = new FixedResponseHandler();
    private readonly HttpMessageInvoker _invoker;

    private const string OwinHandlerBridgeResponse = "OwinHandlerBridge_Response";

    private class FixedResponseHandler : HttpMessageHandler
    {
        protected override Task<HttpResponseMessage> SendAsync(HttpRequestMessage request, 
            CancellationToken cancellationToken)
        {
            return Task.FromResult(
                (HttpResponseMessage)
                request.Properties[OwinHandlerBridgeResponse]);
        }

    }

    public OwinHandlerBridge(DelegatingHandler delegatingHandler)
    {
        _delegatingHandler = delegatingHandler;
        _delegatingHandler.InnerHandler = _fixedResponseHandler;
        _invoker = new HttpMessageInvoker(_delegatingHandler);
    }

    protected override Task<HttpResponseMessage> SendAsync(HttpRequestMessage request, 
        CancellationToken cancellationToken)
    {
        var owinContext = request.GetOwinContext();
        request.Properties.Add(OwinHandlerBridgeResponse, owinContext.Response.ToHttpResponseMessage());
        return _invoker.SendAsync(request, cancellationToken);
    }
}

This bridge turns a DelegatingHandler into a HttpMessageHandler so that I can use .UseHttpMessaageHandler(). But there are problems. First of all, I cannot turn use back an OWIN response body since it is implemented as a write-only stream. Also the process of converting Message to and from OWIN to ASP.NET Web API has been reported to be expensive - and prohibitive.

Another issue is also the difference in pipelines so that an OWIN middleware is different from a DelegatingHandler. In ASP.NET Web API, every DelegatingHandler is visited twice in the pipeline (or none in case of a short-circuiting - shown as faded arrows):


In OWIN, a middleware gets the chance to change the request or response only once (or none in case of a short-circuit - shown as faded arrows):


[Correction: since middleware interface is Task-based, practically every component is called twice and you can re-process in the Task continuation, pretty much similar to ASP.NET Web API]

So here is the question, which model should I build my middleware? While many believe it is OWIN, Dominick Baier (@leastprivilege) has already decided to abstract it away from both and created his own model in Thinktecture.IdentityModel to represent an HTTP request and response. Pedro Felix also believes the same.

And the quest for a common HTTP pipeline paradigm continues...


Thursday, 9 May 2013

Performance series - Announcing SuperBenchmarker sb.exe for generating load on your API/Site

[Level T1] Some of you might be doing performance analysis for living, and if so, you have access to expensive performance tools. But for those who are not and get drawn into investigating performance of their own application or their peers, there is really not a great free tool that you can just point to a URL and hammer.

Well, actually there is: Apache benchmark or ab.exe which has served the community since almost 20 years ago. It is free and very performant, i.e. does not require a lot of resources to run so does not affect the performance even if you benchmark your localhost server. But it has limitations (only GET, no HTTPS, no parameterisation) and I could not find a tool so I ended up writing one for my own use. And now I am sharing it.


SuperBenchmarker or sb.exe is a single-exe (ilmerged with dependencies inside) application that can be used to call various endpoints. It can do GET as well as other verbs, can do request templating and you can provide values for placeholders in URL or your template. It also can output a lot of tracing info in case you need it.

It requires .NET 4.5 but you can target any site or API written in Ruby, PHP, Java, ect. You can download it from here if you do not want to use NuGet. [Update: It has been reported that some people have had issue running on x64 windows. If so please comment on this GitHub issue]

So version 0.1 is out and it works although project needs some love with tests and a few features. There are also some shortcuts taken which needs to be sorted out - but it works.You can clone the code and build it (running build.ps1) or simply use NuGet to download it. [Update: preferred method is using Chocolatey - see below]

PM> Install-Package SuperBenchmarker

For usage, see the wiki on the GitHub. I value feedbacks, also if interested to get involved with the project let me know.


Update

Courtesy of Mike Chaliy, this has now a chocolatey package. So if you have chocolatey installed (and if not here are the instructions), simply run this command in command line:

cinst SuperBenchmarker

Info

Usage:
sb.exe -u url [-c concurrency] [-n numberOfRequests] [-m method] [-t template] [-p plugin] [-f file] [-d] [-v] [-k] [-x] [-q] [-h] [-?]
Parameters:
-u Required. Target URL to call. Can include placeholders.
-c Optional. Number of concurrent requests (default=1)
-n Optional. Total number of requests (default=100)
-m Optional. HTTP Method to use (default=GET)
-p Optional. Name of the plugin (DLL) to replace placeholders. Should contain one class which implements IValueProvider. Must reside in the same folder.
-f Optional. Path to CSV file providing replacement values for the test
-d Optional. Runs a single dry run request to make sure all is good (boolean switch)
-v Optional. Provides verbose tracing information (boolean switch)
-k Optional. Outputs cookies (boolean switch)
-x Optional. Whether to use default browser proxy. Useful for seeing request/response in Fiddler. (boolean switch)
-q Optional. In a dry-run (debug) mode shows only the request. (boolean switch)
-h Optional. Displays headers for request and response. (boolean switch)
-? Optional. Displays this help. (boolean switch)


Examples:

-u http://google.com
-u http://google.com -n 1000 -c 10
-u http://google.com -n 1000 -c 10 -d (runs only once)
-u http://localhost/api/myApi/ -t template text (file contains headers to be sent for GET. format is same as HTTP request)
-u http://localhost/api/myApi/ -m POST -t template.txt (file contains headers to be sent for POST. format is same as HTTP request with double CRLF separating headers and payload)
-u http://localhost/api/myApi/{{{ID}}} -f values.txt (values file is CSV and has a column for ID)-u http://localhost/api/myApi/{{{ID}}} -p myplugin.dll (has a public class implementing IValueProvider defined in this exe)
-u http://google.com -h (shows headers)
-u http://google.com -h -q (shows cookies)
-u http://google.com -v (shows some verbose information including URL to target - especially useful if parameterised)

Tuesday, 19 March 2013

CacheCow Series - Part 0: Getting started and caching basics

[Level T2] CacheCow is an implementation of HTTP Caching for ASP.NET Web API. It implements HTTP caching spec (defined in RFC 2616 chapter 13) for both server and client, so you don't have to. You just plug-in the CacheCow component in server and client and the rest is taken care of. You do not have to know details of HTTP caching although it is useful to know some basics.

It is also a flexible and extensible library that instead of pushing a resource organisation approach down your throat, allows you to define your caching strategies and resource organisation using a functional approach. It stays opinionated only about caching where the opinion is HTTP spec. We shall delve into these customisation points in the future posts. But first let's to caching 101.

Caching

Caching is a very overloaded and confused term in ASP.NET. Let's review the cachings available in ASP.NET (I promise not to make it too boring):

HttpRuntime.Cache

This class is used to cache managed objects in SERVER memory using a simple dictionary like key-value approach. You might have used HttpContext.Current.Cache but it is basically nothing but a reference to HttpRuntime.Cache. So how is this different to using a plain dictionary?
  1. You can define expiry so you do not run out of memory and your cache can be refreshed. This is the most important feature.
  2. It is thread-safe
  3. You can never run out of memory with this even with no expiry. As long as it hits a configurable limit, it purges half of the cache.
  4. And also: it stores the data in the unmanaged memory of the worker process and not in heap so does not lengthen GC sweeps.
This cache is useful for keeping objects around without having to acquire them all the time (could be complex calculation or IO cost such as database). No, this is not HTTP caching.

Output cache

In this approach output of a page or a route can be cached on the SERVER so the server code does not get executed. You can define expiry and let the output cached based on parameters. Output cache behind the scene uses HttpRuntime.Cache.

You guessed it right: this is also not HTTP caching.

HTTP Caching

In HTTP Caching, a cacheable resource (or HTTP response in simple terms) gets cached on the CLIENT (and not server). Server is responsible for defining cache policy, expiry and maintaining resource metadata (e.g. ETag, LastModified). Client on the other hand is responsible for actually caching the response, respecting cache expiry directives and validating expired resources.

The beauty of the HTTP caching is that your server will not even be hit when client has cached a resource - unlike other two types of caching discussed. This helps with minimising the scalability, reducing network traffic and allowing for offline client implementation. I believe HTTP caching is the ultimate caching design.

One of the fundamental differences of HTTP caching with other types of caching is that a STALE (or expired) resource is not necessarily unusable and does not get removed automatically. Instead client call server and check if the stale resource is still good to use. If it is, server responds with status 304 (NotModified) otherwise it sends back the new response.

HTTP Caching mechanism can also be used for solving concurrency problems. When a client wants to update a resource (usually using PUT), it can send a conditional call and ask for update to run if and only if the version of the server is the same as the version of the client (based on its ETag or LastModified). This is especially useful with modern distributed systems.

So as you can see, client and server engage in a dance using various headers and things can get really complex. Good new is you don't have to worry about it. CacheCow implements all of this for you out of the box.

CacheCow consists of CacheCow.Server and CacheCow.Component. These two components can be used independently, i.e. each will work regardless the other is used or not - this is the beauty of HTTP Caching as a mixed concern which I explained here.

CacheCow on the server

How easy is it to use CacheCow on the server? You just need to get the CacheCow.Server Nuget package:

PM> Install-Package CacheCow.Server

And then 2 lines of code to be exact (actually 3 but we will see why):

var cachecow = new CachingHandler();
GlobalConfiguration.Configuration.MessageHeandlers.Add(cachecow);

So with this line of code all your resources become cacheable. By default expiry is immediate so client has to validate and double check if it can re-use the cache resource but all of this can be configured (which we will talk about in future posts). Also server now is able to respond to conditional GET or PUT requests.

CacheCow on the server requires a database (technically cache store) for storing cache metadata - but we did not define a store. CacheCow comes with an in-memory database that can be used if you do not specify one. This is good enough for development, testing and small single server scenarios but as you can imagine not scalable. What does it take to define a database? Well, a single line hence the 3rd line and you can choose from SQL Server, Memcached,  RavenDb (Redis to come soon) or build your own by implementing an interface against another database (MySql for example).

So in this way we will have 3 lines (although you may combine first two lines):

var db = new SqlServerEntityTagStore();
var cachecow = new CachingHandler(db);
GlobalConfiguration.Configuration.MessageHeandlers.Add(cachecow);

With these three lines, you have added full feature HTTP caching (ETag generation, responding to conditinal GET and PUT, etc) to your API.

CacheCow on the client

Browsers that we use everyday (and usually even forget to look at as an application) are really amazing HTTP consumption machines. They implement cache storage (file-based) and are capable of handling all client scenarios of HTTP caching.

Client component of CacheCow just does the same but is useful when you want to use HttpClient for consuming HTTP services. Plugging it into your HttpClient is as simple as the server side. First get it:
PM> Install-Package CacheCow.Client
Then

var client = new HttpClient(new CachingHandler()
       { 
           InnerHandler = new HttpClientHandler()
       });


In a similar fashion, client component of CacheCow requires a storage - and this time for the actual responses (i.e. resources). By default, an in-memory storage is used which is OK for testing or single server and small API but for persistent stores you would use from stores such as File, SQL Server, Redis, MongoDB, Memcached aleady implemented or just implement the ICacheStore interface on the top of an alternative storage.

Constructor of the client CachingHandler accepts an implementation of ICacheStore which is your storage of choice.

So now cacheable resource will be cached and CacheCow will do conditional GET and PUT for you.

In the next post, we will look into server component of CacheCow.

Monday, 18 March 2013

CacheCow 0.4 released: new features and a breaking change

Version 0.4 is out and with it a couple of features such as attribute-based cache control and cache refresh (see below). For the first time I felt that I have got to write a few notes about this version, least of which because of one breaking change in this release - although it is not likely to break your code as I explain further. Changes have been in the server components.

I and other contributors have been working on CacheCow for the last 8 months. I thought with a couple of posts I have explained the usage of CacheCow. But I now feel that with concept counts increasing, I need to start a series on CacheCow. Before doing that I am going to explain new concepts and the breaking change.

Breaking change

The breaking change was a change in the signature of CacheControlHeaderProvider from Func<HttpRequestMessage, CacheControlHeaderValue> to Func<HttpRequestMessage, HttpConfiguration, CacheControlHeaderValue> to accept HttpConfiguration.

If you have provided your own CacheControlHeaderProvider, you need to provide HttpConfiguration as well - which should be very easy to fix whether web-host or self-host.

Cache Control Policy

So defining cache policy against resource have been by setting the value of CacheControlHeaderProvider which you would define whether a resource is cacheable and if it is, what is the expiry (and other related stuff):

public Func<HttpRequestMessage, HttpConfiguration, CacheControlHeaderValue> CacheControlHeaderProvider { get; set; }

So by default CacheCow sets Func to return a header value for private caching with immediate expiry for all resources:

CacheControlHeaderProvider = (request, cfg) => new CacheControlHeaderValue()
{
 Private = true,
 MustRevalidate = true,
 NoTransform = true,
 MaxAge = TimeSpan.Zero
};

Immediate expiry actually means that the client can use the expired resource as long as it validates the resource using a conditional GET - as explained before here.

But what if you want to individualise cache policy for each resource? We could use per-route handlers but that is not ideal and generally it depends on the resource organisation approach. I have explained in my previous post that resource organisation is one of the areas that needs to be looked at. But this is not within the scope of CacheCow. We are looking into solving this as part of another project while ASP.NET team are also looking into this. So I have decoupled the resource organisation project from CacheCow.

Having said that, in the meantime, I am going to provide some help with doing cache policy set up less painful. This means that CacheCow will come with a few pre-defined functions that help you with defining your cache control policy.

Good news! Cache policy definition using attributes

So now you can define your cache policy against your actions or controllers or both - although action attribute always takes precedence over controller. Using the popular ASP.NET Web API sample:

    [HttpCacheControlPolicy(true, 100)]
    public class ValuesController : ApiController
    {

        public IEnumerable<string> Get()
        {
            return new[] { "cache", "cow" };
        }

        [HttpCacheControlPolicy(true, 120)]
        public string Get(int id)
        {
            return "cache cow... mooowwwww";
        }

So GET call to the first action (/api/Values) will have a max-age of 100 while GET to the second action (e.g. /api/Values/1) will return a max-age of 120.

In order to set this up, all you have to do is to set the CacheControlHeaderProvider property of your CachingHandler to GetCacheControl method of an instance of AttributeBasedCacheControlPolicy:

cachingHandler.CacheControlHeaderProvider = new AttributeBasedCacheControlPolicy(
 new CacheControlHeaderValue()
  {
   NoStore = true
  }).GetCacheControl;

So in above we have passed a default caching policy of no-caching. This table defines which attribute value (or default provided in the constructor) is used:


Cache Refresh Policy

CacheCow works best when HTTP API is actually a REST API. In other words, it uses uniform interface (i.e. HTTP Verbs) to modify resources and this means that the caching handler will get the opportunity to invalidate and remove the cache when POST, PUT, DELETE or PATCH is used.

Problem is commonly HTTP API sits on the top of a legacy system where it has not control over modifications of resources and acts as a data provider. In such a case, the API will not be notified on resource changes and application will be responsible for removing cache metadata directly on the EntityTagStore used. And this is not always possible.

I am providing a solution for defining a time based cache refresh policy using attributes in a very similar fashion to Cache Control Policy - even the above table applies. Removal of items from cache store on the server happens upon the first request after the refresh interval has passed not immediately after interval. So we add the refresh policy provider:

cachingHandler.CacheRefreshPolicyProvider = new AttributeBasedCacheRefreshPolicy(TimeSpan.FromSeconds(5 * 60 * 60))
    .GetCacheRefreshPolicy;

We have defined 5 hour refresh policy as default. And we override using controller or action attributes.

Future posts

As promised, next few posts will be a CacheCow walk-through.